The Judicial Challenge to Algorithmic Training Integrity
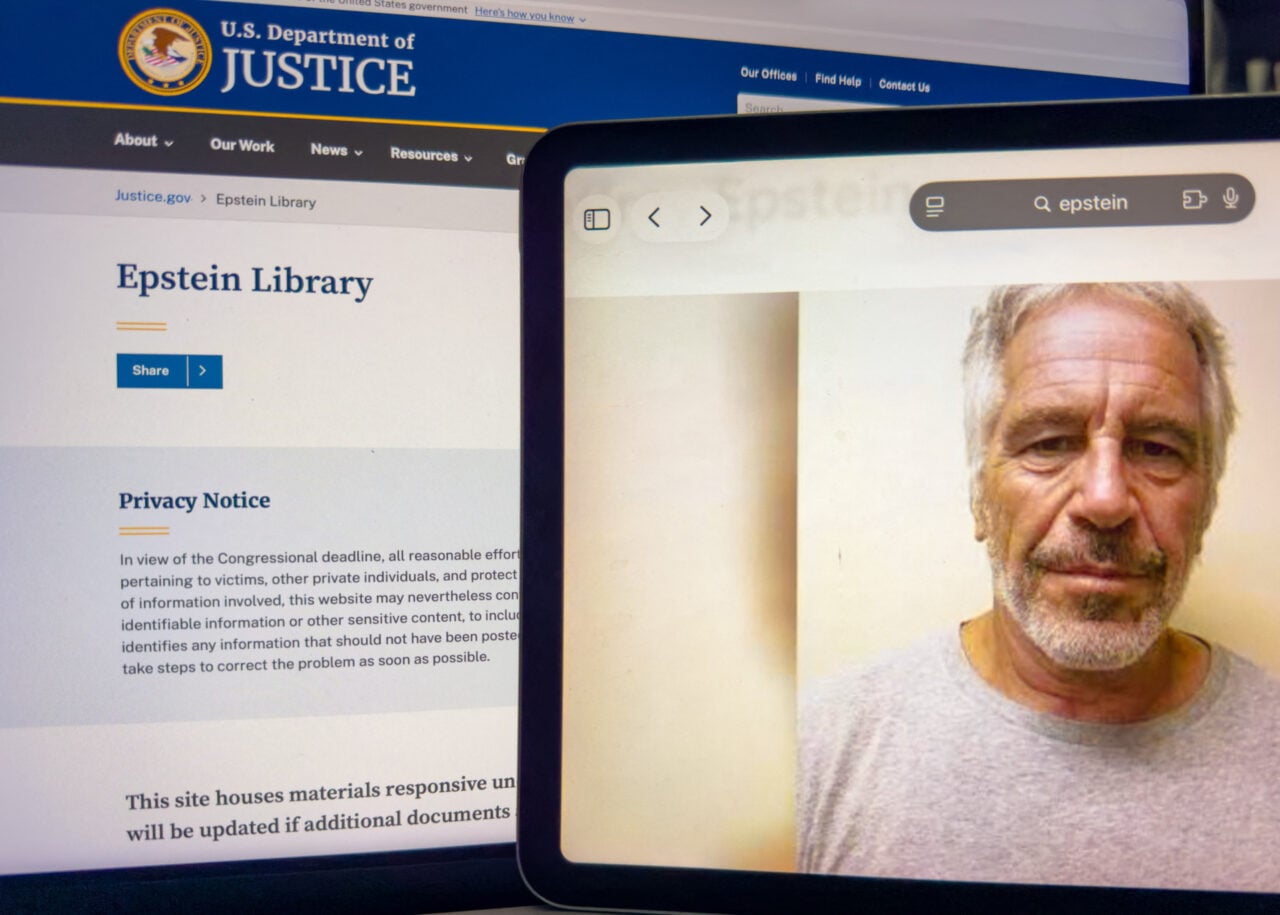
The recent litigation initiated by victims of Jeffrey Epstein against Google marks a watershed moment in the intersection of artificial intelligence and privacy law. The plaintiffs allege that Google's AI models—specifically those within the Gemini and Bard ecosystem—exposed sensitive personal information that should have remained shielded from the public domain. This case transcends simple data leakage; it questions the very foundation of how tech conglomerates harvest and utilize massive datasets for training.
The core of the grievance lies in the assertion that the AI surfaced private details derived from leaked documents and non-public records, effectively acting as an automated vector for doxing.
From a strategic intelligence perspective, this lawsuit highlights the fragility of current data scrubbing protocols. Tech giants have long operated under the assumption that the sheer scale of training data would obfuscate individual identities. However, the ability of Large Language Models (LLMs) to reconstruct specific narratives from fragmented data points suggests a systemic failure in anonymization.
For Google, the legal stakes are compounded by the reputational risk of being perceived as an entity that profits from the digital echoes of trauma. This is no longer a theoretical debate about AI ethics; it is a direct challenge to the industrial standards of data ingestion.
The Technical Paradox of Memorization versus Generalization
At the heart of this controversy is a phenomenon known as 'data memorization.' While the goal of an LLM is to generalize patterns across a vast corpus of text, these models frequently 'overfit' on specific, high-weight strings of information. This leads to the unintentional regurgitation of verbatim training data when prompted with specific, often obscure, queries.
In the context of the Epstein victims, the AI's output reportedly included addresses, contact information, and specific details of their experiences that were never intended for algorithmic processing. This reveals a critical vulnerability in the 'black box' nature of proprietary models.
Current mitigation strategies, such as Reinforcement Learning from Human Feedback (RLHF), are designed to prevent the generation of harmful content, yet they often fail to address the underlying presence of sensitive data within the model's weights.
The industry is now facing a technical reckoning: if a model cannot distinguish between public knowledge and private data during the training phase, the risk of 'unintended disclosure' becomes an inherent feature rather than a bug. Strategic analysts must recognize that as AI becomes more sophisticated, its capacity to connect disparate pieces of private information increases exponentially, creating a new frontier of digital exposure.
Redefining Liability in the Age of Generative Intelligence
The legal framework surrounding this case threatens to dismantle the traditional protections afforded to tech platforms. Historically, Section 230 of the Communications Decency Act has shielded companies from liability for content created by third parties. However, when an AI model synthesizes and outputs sensitive information, the distinction between 'platform' and 'creator' becomes dangerously blurred.
The plaintiffs argue that Google is not merely hosting information, but actively generating new, harmful iterations of that data through its algorithmic processes. This shift in legal interpretation could set a precedent where AI developers are held strictly liable for the outputs of their models.
Furthermore, the global regulatory environment is rapidly tightening. With the EU AI Act and similar frameworks gaining traction, the requirement for 'privacy by design' is moving from a recommendation to a mandate.
Corporations must now account for the 'unlearning' of sensitive data—a process that is technically complex and computationally expensive. The Epstein lawsuit serves as a catalyst for a broader discussion on the economic viability of training models on unverified or ethically compromised datasets. The cost of litigation and potential fines may soon outweigh the competitive advantages of rapid AI deployment.
The Imperative for Differential Privacy and Data Governance
The strategic verdict is clear: the era of unrestrained data harvesting is over. To survive the coming wave of litigation, tech leaders must pivot toward advanced data governance techniques, such as differential privacy and federated learning.
Differential privacy, which injects mathematical 'noise' into datasets to prevent the identification of individuals, is no longer an academic luxury—it is a strategic necessity. The Epstein case demonstrates that any failure to implement these safeguards can result in catastrophic legal and social consequences.
Organizations must prioritize the integrity of their training pipelines over the sheer volume of data.
In the present industrial context, the focus must shift from 'more data' to 'better data.' This involves rigorous auditing of datasets to ensure that PII (Personally Identifiable Information) is purged before it ever touches a GPU.
The move toward smaller, high-quality, and ethically sourced datasets is not just a trend; it is a defensive posture against an increasingly litigious landscape. Google's current predicament is a warning to the entire sector: the algorithms we build are only as secure as the data they consume. In the high-stakes game of global AI dominance, privacy is becoming the ultimate competitive differentiator.